Key takeaways
- Most AI deployments log HTTP traffic but not the model's input, tool calls or output chain. The attack surface goes unwatched.
- Every tool call an LLM makes needs an audit record: which function, what parameters, what the tool returned and what the conversation context was at the time.
- Output scanning is an outbound data control. Flag PII patterns, unexpected code blocks and policy classifier near-misses in every model response.
- Session-level correlation across turns is the only reliable way to catch a gradual prompt injection or data extraction chain.
- CBUAE, DESC and ADHICS all require audit trails for automated systems that process customer or patient data. An LLM deployment either satisfies that requirement or it does not.
The logging gap most AI deployments ship with
Traditional application logging captures HTTP requests, database queries and authentication events. An AI application adds a layer that most logging stacks have no rules for: a natural-language interface that can receive instructions, interpret them as commands and act on external systems. Without instrumentation at the model layer, a prompt injection or tool call abuse can run to completion with no record of what was asked or what happened.
The data exists. The model API returns inputs, outputs and tool invocations in structured form. Most deployment teams treat the model as a black box, though, passing responses on without retaining the chain. An AI and LLM pentest tests that chain in full. The finding is often not that an attack worked but that nothing logged it when it did. A vulnerability with no detection signal is one the client cannot meaningfully remediate.
Input-layer telemetry: what to capture before the model sees it
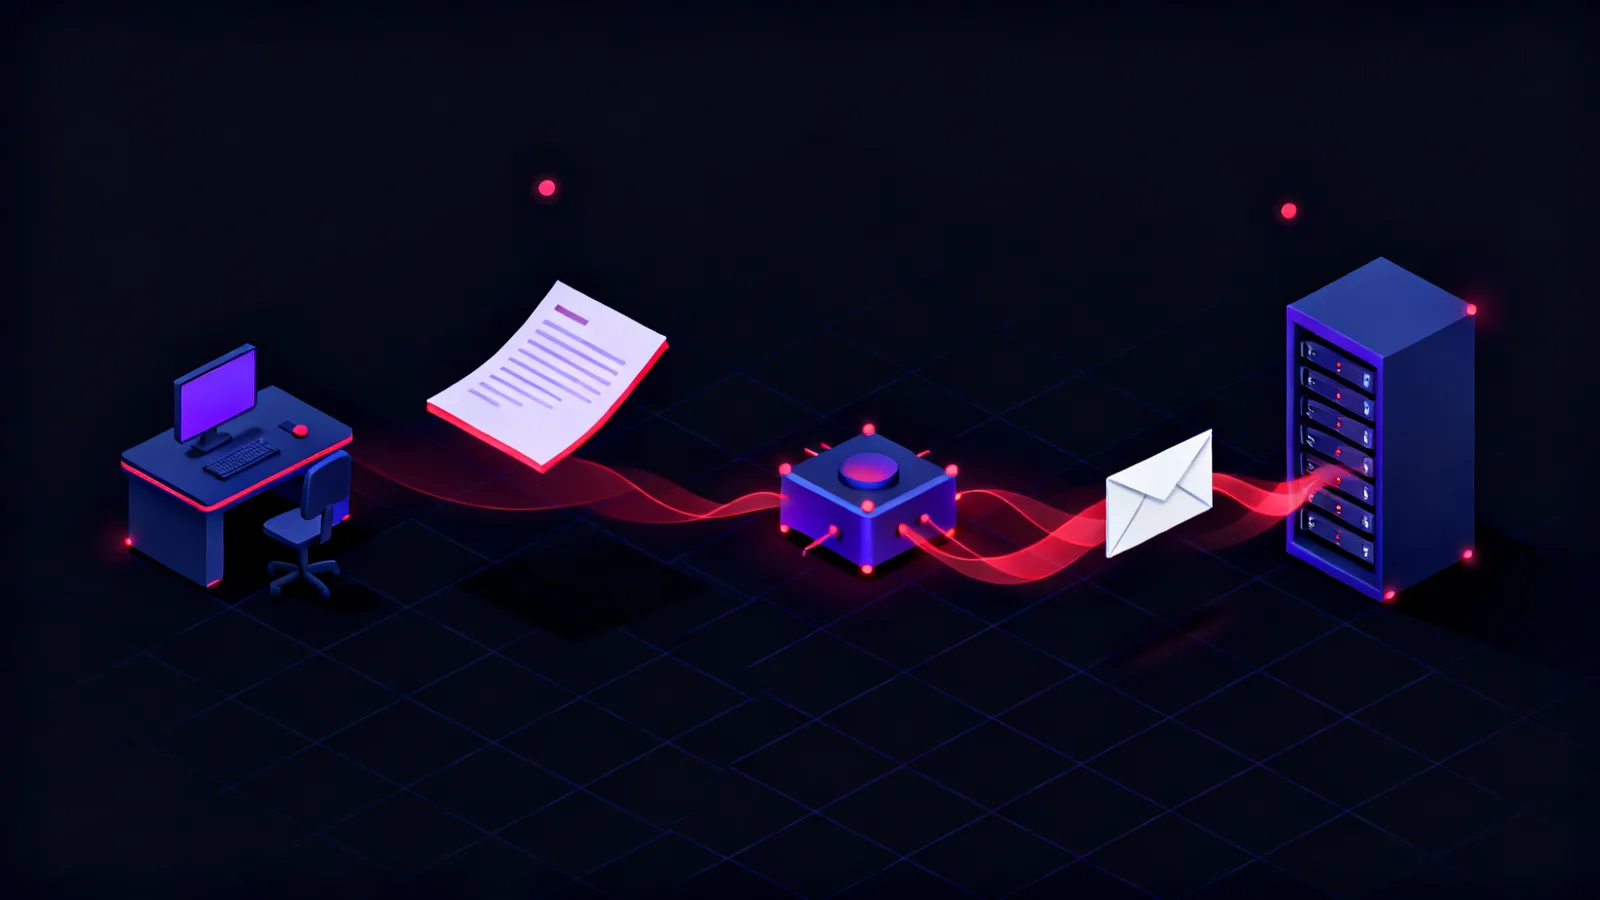
The input layer is where a direct prompt injection first appears. Log the raw user message, the session identifier, the user account, the channel (API key, web interface, integrated agent), the timestamp and the input token count. Do not log only the processed or sanitised version. The injection is in the raw input, and a sanitiser that fails silently leaves no trace of the attempt.
Monitor for anomalous patterns in the input itself. Unusual character sequences that signal escape attempts, such as repeated newlines followed by role markers, Base64-encoded payloads in a plain-text field or XML-style tags injected into natural language, are worth flagging even when they do not succeed. OWASP's Top 10 for LLM Applications lists prompt injection as the leading risk class, and the detection foundation is the same as for any injection family: you cannot catch what you cannot see.
Log the system prompt version hash on every request. A deployment whose system prompt changes in response to user input, or one where the system prompt can be read back through a crafted query, will show that change in the retained record. Hash drift outside a deployment event is worth alerting on.
Input
Message captured
Raw input, token count, session ID, channel
System prompt versioned
Hash logged on every request to detect drift
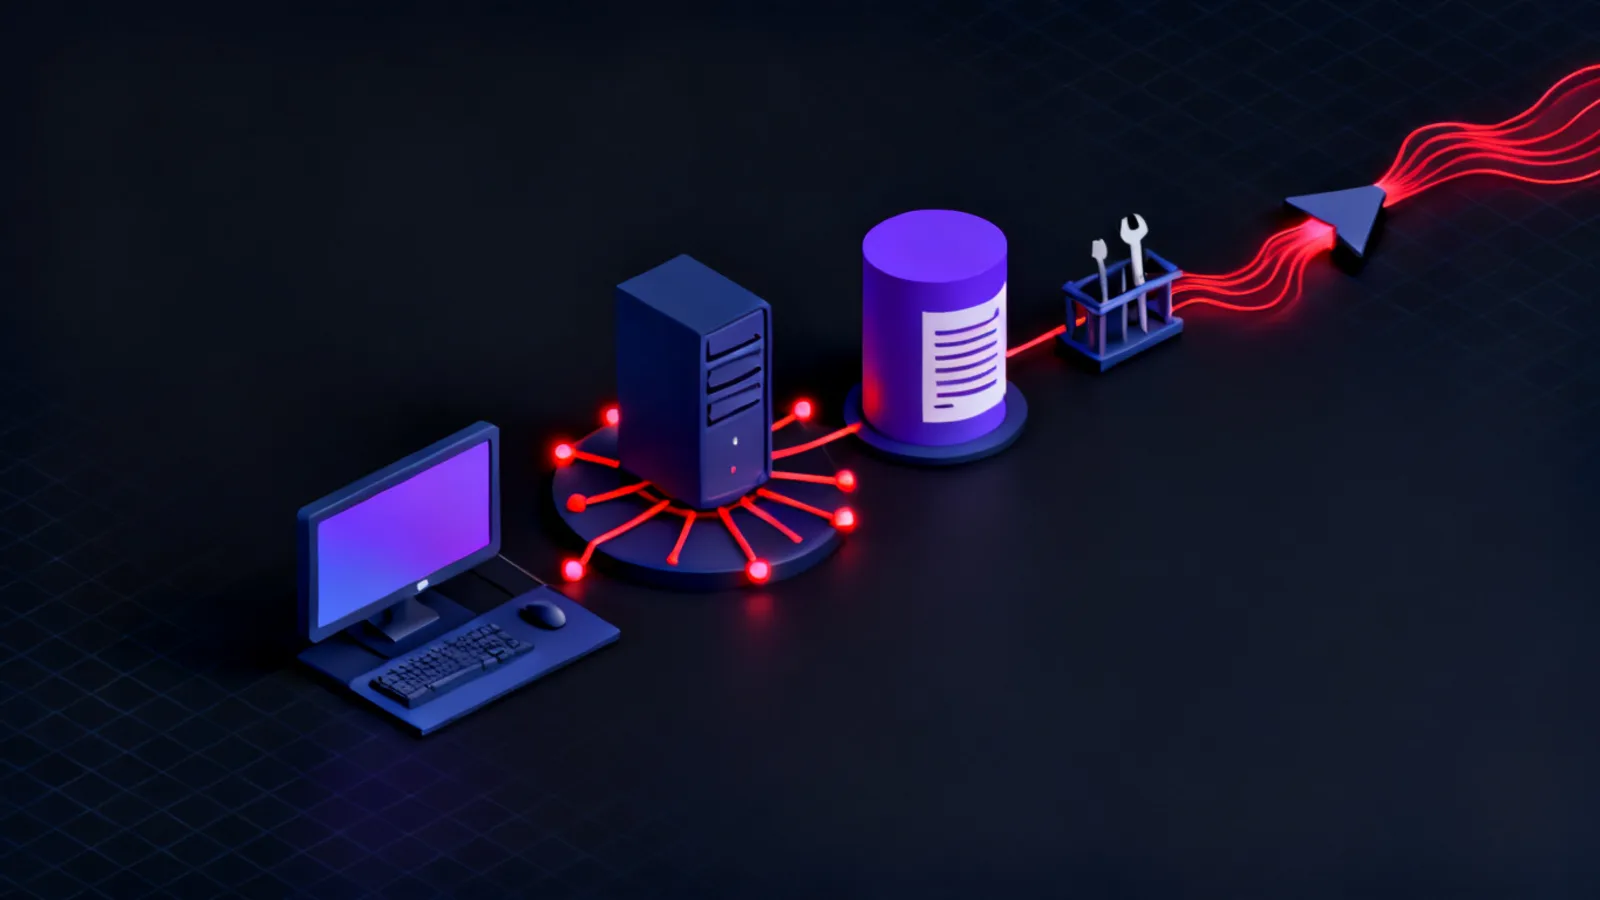
Inference
Model call
Input and output token counts, latency
Tool invocations
Function name, parameters, return value, sequence
Policy classifier
Result and confidence on every response
Output
Response delivered
Scanned for PII, unexpected code, policy bypass
Chain retained
Session ID links all events for cross-turn correlation
Tool call telemetry: what every function invocation must emit
An LLM application with tool access is an agent that can act on external systems. Each action needs an audit record: which tool was called, what parameters were passed, what the tool returned, whether the call was initiated by a user instruction or generated by the model on its own, and what the conversation context looked like at the time. Without that record, a model instructed through retrieved content to exfiltrate data leaves nothing in the standard application log. Indirect prompt injection is this class of attack. The instruction arrives in content the model fetched, not in the user's own message, so the input-layer log shows nothing unusual.
Watch for tool calls that do not match the user's intent. A customer service agent that calls a file-read function when the user asked about an invoice is a mismatch worth investigating. Log the full tool call chain, not only the final response. An agent that calls tool A to retrieve data, passes it to tool B and sends the result to an external endpoint may look unremarkable at each step. The anomaly is in the sequence.
The AI and LLM pentest methodology tests tool call boundaries directly: what functions can be called with what parameters, whether tools can be chained in unintended ways and whether the model can be instructed to bypass tool constraints. Without tool call logging, the test findings have no detection anchor. The vulnerability is named, but the signal that would catch it in production is absent. The gap persists after the remediation is marked closed.
{
  "session_id": "sess_a3f7b9d2",
  "turn": 4,
  "event": "tool_call",
  "tool": "read_file",
  "parameters": { "path": "/etc/passwd" },
  "initiated_by": "model",
  "user_intent_turn_3": "What is the current weather?",
  "policy_check": "pass",
  "flagged": false
}
Output analysis: scanning what the model sends back
The model's response is data leaving the system. Treat it as an outbound data stream and apply the same scanning you would to any other: PII patterns, credential-shaped strings, code blocks in contexts where code was not requested and fragments that resemble the system prompt. A customer support model that returns a block of SQL or a JSON object containing internal configuration is worth alerting on, even if the user asked a benign question.
Policy classifier output is a specific signal to retain. Most production deployments run the model response through a classifier before delivery. Log the result on every response, including the confidence score, not only the ones the classifier flags. An attack series that walks gradually toward a policy violation produces near-misses in the classifier output before the eventual flag. That gradient is only visible in the retained log. NIST SP 800-115 defines continuous monitoring as a technical security control, and model output scanning is what that obligation looks like in an AI system.
| Attack class | Log field to retain | Alert condition | Severity |
|---|---|---|---|
| Direct prompt injection | Raw user input, session ID | Injection marker patterns in input text | High |
| Indirect prompt injection | Retrieved external content before model ingestion | Instruction-like patterns in fetched data | High |
| Tool call abuse | Function name, parameters, caller context | Tool called outside intended scope or with anomalous parameters | High |
| Jailbreak or policy bypass | Full model response, classifier result | Classifier confidence below threshold or override detected | High |
| System prompt extraction | Full model response | System prompt fragments appearing in output | Medium |
| Context window flooding | Token count per turn, cumulative session tokens | Token spike beyond session baseline | Medium |
| Data exfiltration via output | Output content, destination channel | PII pattern or credential-shaped string in response | High |
Session-level correlation: detecting the chain, not the step
Context window flooding sends unusually long messages to consume the model's attention, degrading output quality or burying instruction content in noise. Token count per turn is a straightforward metric to retain and a simple rule to alert on: a turn an order of magnitude above the baseline for that application is worth reviewing regardless of content.
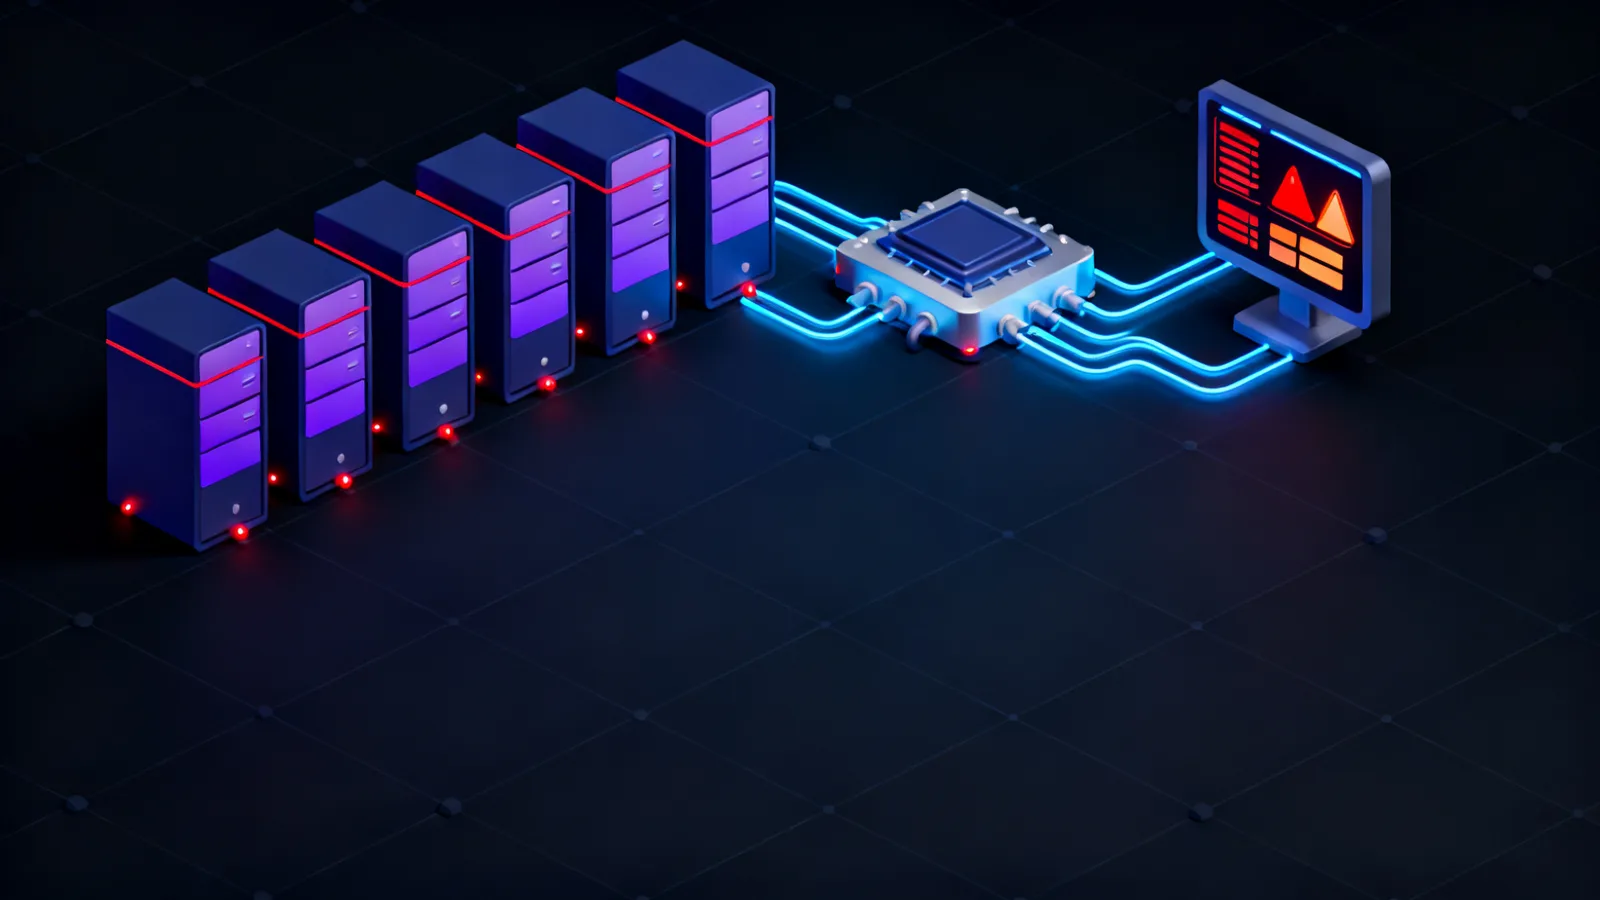
Session-level correlation is the harder and more important class of detection. A sophisticated attack rarely lands in a single turn. Map the sequence: input anomalies in turns one and two, a tool call that does not match user intent in turn three, output with PII characteristics in turn four. No single event trips the alert. The combination does. This requires retaining the full session context, indexed by session ID, and writing rules that reason across turns rather than per message.
MITRE ATT&CK documents the tactics and techniques an attacker uses after initial access. The framework applies equally to AI systems. Reconnaissance maps to probing the system prompt, credential access maps to extracting API keys from tool responses, lateral movement maps to using one tool to reach systems outside the agent's intended scope and exfiltration maps to having the model return data it should not have. Mapping log events to ATT&CK categories gives the detection rule set a structure that survives changes to the AI layer. A purple team session that runs these patterns against a live AI application, with a red team mapping findings to ATT&CK categories, is the fastest way to check whether the instrumentation holds before a real incident does.
Alert urgency
Tool call abuse
Unexpected function with attacker-controlled parameters. One record fires the alert.
Exfiltration chain
PII accumulates across turns before the final output event. Alert needs the full session.
Blocked injection
Injection marker in input, attempt failed. Log and review; no immediate response needed.
Context flooding
Token count grows across turns. Alert on session total, not on any single message.
Correlation required
AI system logging obligations in the UAE market
The Central Bank of the UAE's Technology Risk Management Circular requires financial institutions to maintain audit logs for all automated systems that process customer data. An LLM deployed in a UAE bank's customer service, onboarding or fraud detection workflow is an automated system under that framework. The absence of input and output logging is a direct control gap in an audit. The CBUAE framework does not name large language models by name, but the principle is clear: if the system acts on customer data, the action must be auditable. For the governing text, see the CBUAE's published guidance.
Dubai's DESC framework for government digital services requires evidence that AI-assisted tools have audit trails capable of supporting forensic review after an incident. Organisations supplying digital services to Dubai government entities, including those in free zones such as Dubai Silicon Oasis, must meet that requirement before deploying an AI-powered feature to production. In Abu Dhabi, ADHICS applies to any system that generates or processes patient-facing output, including AI assistants deployed by Abu Dhabi Health Services Company licensees. The standard requires that automated system events be retained in a form that supports incident investigation.
At the federal level, the UAE Information Assurance Standard published by NESA requires organisations classified as critical national infrastructure to apply continuous monitoring across their digital estate. An AI application that processes data affecting national infrastructure, such as an energy company's operations assistant or a government document processing agent, falls inside that scope. The UAE rules that apply to AI and LLM systems covers the regulatory layer in more detail. Across all three tiers, the obligation is the same: the system must account for what happened. An AI deployment with no model-layer telemetry cannot meet that obligation, and a pentest that does not identify the gap is incomplete.
Frequently asked questions
What is AI application logging and why is it different from standard application logging?
AI application logging captures the model-specific layer that standard logging misses: the raw prompt, the tool calls the model made, the policy classifier result and the full model response before any post-processing. Standard application logs record HTTP traffic and database calls. They do not show what instruction the model received or what action it took on its own. Without the model-layer record, a prompt injection or tool call abuse leaves no trace in the standard log.
How does prompt injection appear in application logs?
A direct prompt injection appears as an anomalous pattern in the raw user input: role-marker sequences, Base64-encoded instructions or XML-like tags in a field intended as plain text. An indirect prompt injection does not appear in the user input at all. It shows up in the content retrieved from an external source before it was passed to the model, so detection depends on logging the retrieved content separately from the user message.
What should a tool call log entry contain?
A tool call log entry should contain the tool name, the full parameter set passed to it, the return value, the session ID, the turn number, whether the call was initiated by the user or generated by the model on its own, and a reference to the user message that was current when the call was made. That last field is what lets an analyst identify intent mismatch: a file-read call made while the user was asking about the weather is a clear anomaly only if the context is retained.
How does indirect prompt injection differ from direct prompt injection in the log record?
Direct prompt injection shows in the input log: the malicious instruction is in the user's own message. Indirect prompt injection shows only in the retrieved-content log: the instruction was embedded in a web page, document or database record that the model fetched as part of its reasoning. If retrieved content is not logged separately from user input, an indirect injection leaves no record of how the model came to take an unexpected action.
What output patterns indicate a jailbreak attempt succeeded?
A policy classifier confidence score below the deployment threshold, or a response that contains code where code was not requested, is the clearest signal. System prompt fragments appearing verbatim in the model response indicate the model was instructed to reveal its configuration. Credential-shaped strings, PII patterns or structured data the model should not have access to are also worth alerting on, regardless of whether the classifier flagged them.
How does session-level correlation improve AI attack detection?
Most AI attacks span multiple conversation turns. A single turn may show a minor anomaly that does not reach an alert threshold on its own. Session-level correlation retains all events under a shared session ID and builds rules that look for combinations: input anomaly in turn two, tool call mismatch in turn three, PII in output at turn four. The combination fires the alert that no individual event would have triggered.
How do AI application logs integrate with a SIEM?
AI application logs are structured JSON and integrate with any SIEM that can ingest JSON over a log shipping agent or a webhook. The practical challenge is not the format but the schema: most SIEM rule sets were written for network and authentication events, so tool call and model output events need custom parsers and correlation rules. Define the schema before deployment and validate it during the AI and LLM pentest, so the rules are in place before the first production incident.
What OWASP or NIST standard covers AI application logging?
OWASP's Top 10 for LLM Applications covers prompt injection, insecure output handling and sensitive information disclosure, all of which carry logging and detection implications. NIST SP 800-115 covers technical security testing including continuous monitoring, and applies to AI systems as it does to any other. Neither standard specifies log schemas for AI systems, but both establish the obligation to detect and retain evidence of attacks. The model-layer telemetry described here is designed to satisfy that obligation.
How does an AI pentest use log telemetry as a detection baseline?
An AI and LLM pentest run with detection instrumentation in place treats the log as the second test artefact, alongside the vulnerability list. Each technique the tester runs should appear in the log in a detectable form. Where it does not, the finding is not only that the attack worked but that the monitoring would not have caught it. That second finding is often the more actionable one: it names exactly which log field to add and which alert rule to write.